Quality Is Our Qualification: Meet the Verified Intelligence Platform
Rep Data Team · November 5, 2026 · 6 min read
On November 3, 2026, RepData launched the Verified Intelligence Platform (VIP): one place to take a study from business question to trusted insight, with quality checks applied at every step. It is built on an idea we call verified intelligence: research where every source, respondent, and response is checked and scored, and what we learn flows back into the study while it is still running.
You shouldn't have to make high-stakes decisions on questionable data. Yet research is often built from separate pieces: one tool for sample, another for quality, another to program and run the study. When those tools don't talk to each other, you manage the gaps between them and hope nothing slipped through.
Whether you already rely on RepData for sample sourcing and fraud prevention, or you have heard our name and want the full picture, this blog walks through how the platform works and why quality is built in rather than bolted on.
Why separate research tools leave gaps
A quality tool that sits apart from your sample and your survey only sees part of the picture. The sample provider doesn't know what happens once respondents are in the survey. The quality check doesn't know where respondents came from. Neither can tell the other what it has learned.
The result is that problems surface late, often after fielding, when the only fix is to replace completes and explain the delay. For enterprise teams making pricing, launch, or campaign decisions on the results, that is a risk worth designing out.
Inside one platform, the picture is complete, and the pieces can act on what they learn together.
How the closed loop works
The verified intelligence closed loop follows every respondent through three stages (source, respondent, and response) and feeds what it finds back into the next decision. That feedback is the loop.
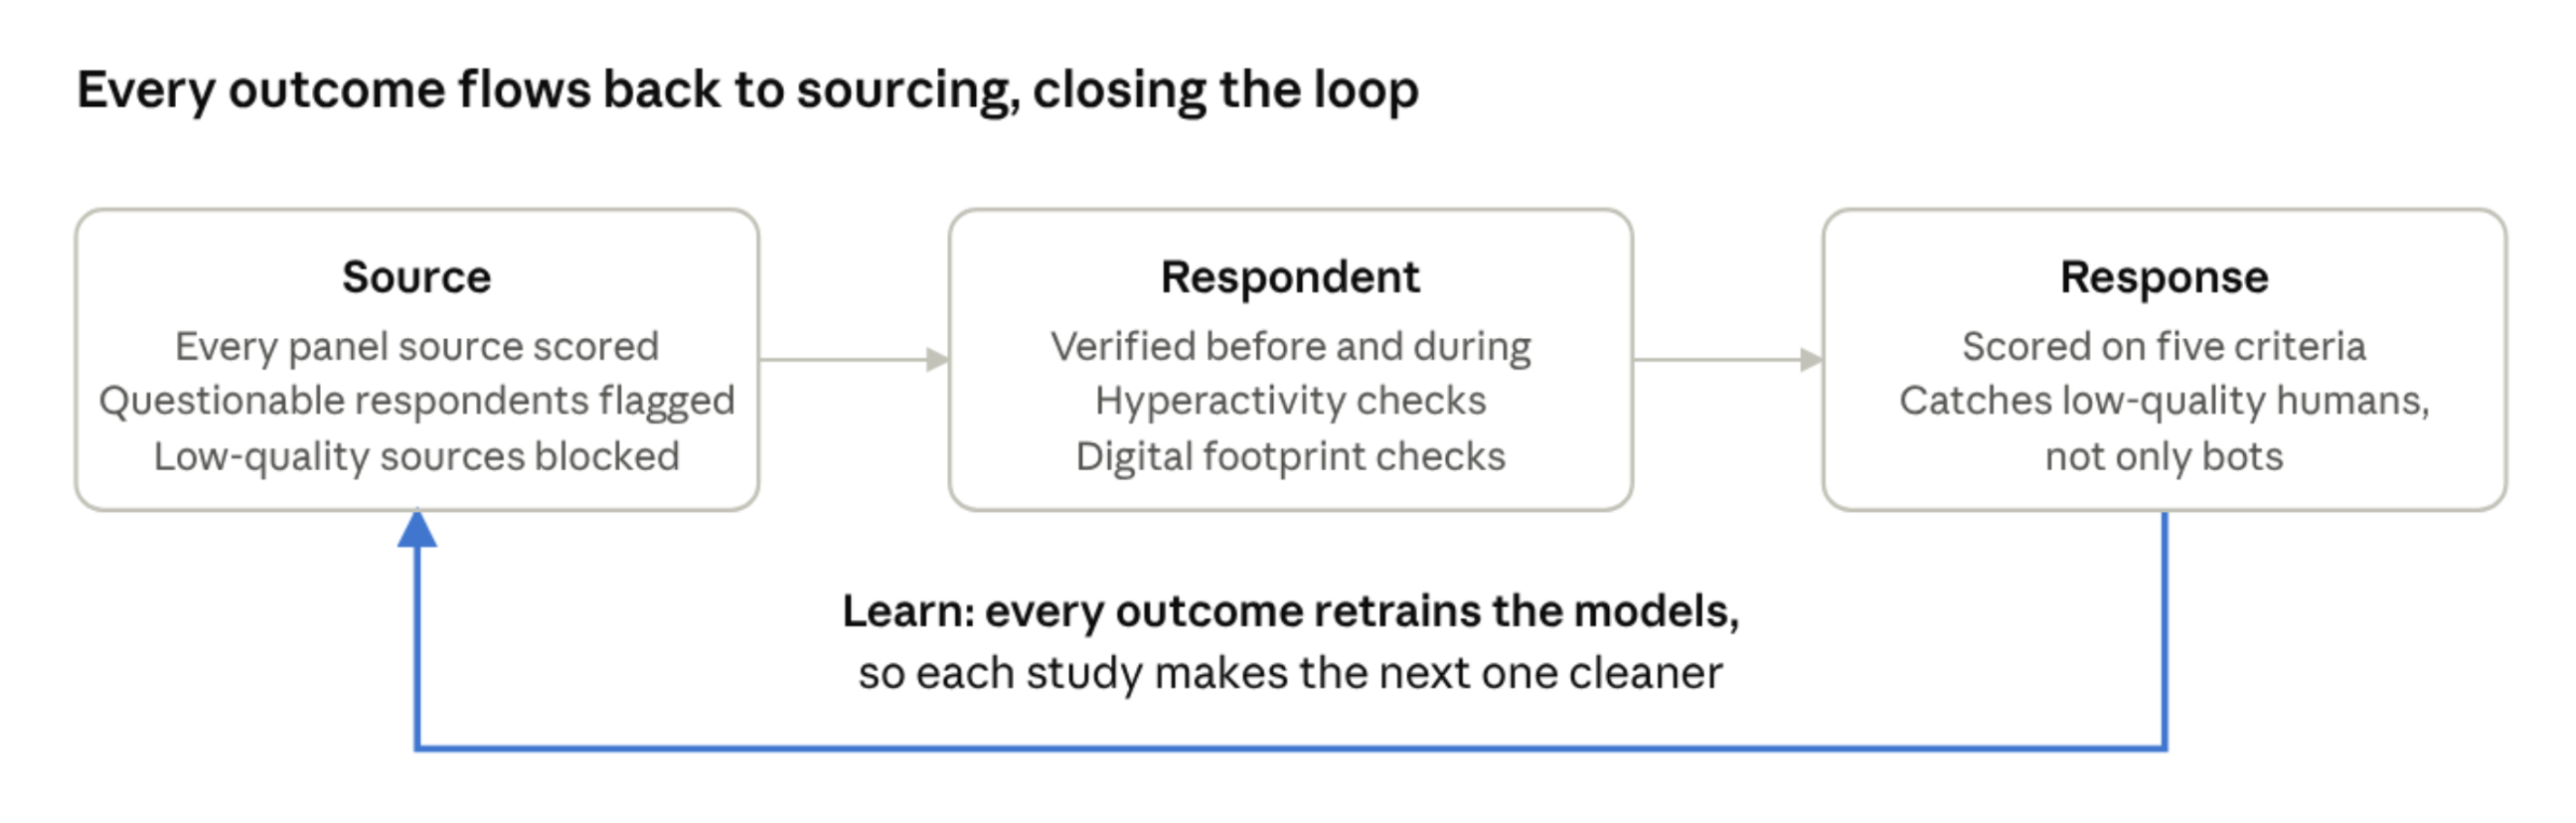
Each respondent is checked at all three stages:
Source. We score every panel source, flag inattentive and questionable respondents, and block sources that supply low-quality respondents, both before your survey and during fielding.
Respondent. We verify each respondent before and during the survey, including checks for hyperactivity (people taking an unusually high number of surveys) and digital footprint.
Response. We score every response on five criteria, so we catch low-quality human responses, not only bots, in ways the human eye can often miss.
The loop closes with learning: every outcome retrains our models, so each study makes the next one cleaner.
The five response-scoring criteria
| Criteria | What we look at |
|---|---|
| Open-ended answers | Whether written responses are relevant and genuine |
| Coherence | Whether a respondent's answers are consistent with one another |
| Grids | Patterns across grid questions, such as straight-lining |
| Time | How long respondents take to complete the survey |
| Behavior patterns | Mouse movement, click patterns, and keystroke cadence |
What the loop looks like in a live study
Imagine a study in the field. Partway through, one panel source starts delivering low-quality respondents. Here is what happens inside the platform:
Response scores flow back to sourcing.
The source is blocked while the study is still running.
Removed respondents are backfilled automatically.
When the quality check and the sample source are separate tools, they don't share what they learn, so the same problem is much harder to catch mid-study. The loop only works when sourcing, the survey, and quality share one system. That also means no stitching tools together through APIs, so you move faster.
The full research cycle, in one place
Quality is the foundation, but the platform covers the whole cycle, from first question to final insight:
Run rigorous research. 50+ methodologies and question types, including conjoint (how people trade off features and price), MaxDiff (what matters most), and TURF (which mix of options reaches the most people), plus deep programming for precision in every study.
Reach high-quality audiences. 250+ sample sources globally give us access to every audience type:
Global B2B and B2C audiences
Custom B2B recruitment
Low-incidence behaviors
Census-balanced samples
Longitudinal studies with lockouts
Trust the data. Our quality stack called Research Defender, including automated data cleaning, protects every study.
Get to the answer faster. Automated analysis and AI-powered recommendations turn results into next steps.
We were deliberate about every tool we brought into the platform, because each had to be best in class at its job. The result is that you run a study from start to finish in one place, with no handoffs between tools. Teams move faster and run more research in less time.
Prefer to keep your current survey tool? Our sample marketplace and quality stack are also available through API and MCP connections, so you can use them with the tools you already have.
Work with our research experts. Technology is only part of verified intelligence. Our research team acts as an extension of yours and can scope, design, field, analyze, and report your projects end to end, whether you want a partner for the whole study or support on specific stages.
What it looks like in practice: how Pabst did more with its research budget
Pabst cut its brand tracking costs by more than 80%, then put the savings to work. It reinvested the dollars into a record number of projects, tested 40+ concepts, and ran advanced methods its old tools couldn't, including conjoint, TURF, and pricing research.
The savings mattered because of what they funded: more research, on more questions, from a more agile team. Read more here.
Frequently asked questions
What is verified intelligence?
Verified intelligence is research where every data source, respondent, and response is checked and scored, and what is learned feeds back into the study while it is still running. RepData's Verified Intelligence Platform (VIP) is built on this closed-loop approach.
How is quality different when it's built in?
Our quality stack follows the whole respondent lifecycle (source, respondent, and response) and learns from every outcome. A standalone tool only sees the part of the process it is connected to.
Can the platform catch low-quality responses that aren't bots?
Yes. We score every response on five criteria: open-ended answers, coherence, grids, time, and behavior patterns such as mouse movement, click patterns, and keystroke cadence. Together they catch low-quality human responses, not only bots.
Do I need the whole platform to work with RepData?
No. The platform gives you everything in one place and the benefit of a closed-loop environment that prevents low-quality responses and fraud. But our sample marketplace and quality stack are also available through API and MCP connections, so you can use them with the survey tools you already have.
What kinds of research can I run?
Teams use the platform for foundational insights like brand tracking and attitudes and usage, innovation work like concept, claims, flavor, and price testing, marketing work like ad and message testing, and shopper research like path-to-purchase.
Can I get help running my studies?
Yes. Our team of research experts can scope, design, field, analyze, and report your projects end to end.
One platform for the whole cycle
If you already trust RepData for sample or quality, you can now run your research with us too, with the same standard applied from first question to final insight. If you are new to the full platform, here are two ways to see it:
Join our upcoming webinar on November 19. Our leaders introduce verified intelligence and show the survey platform, including the closed-loop quality story, with live Q&A.
Book a demo or talk to our research team. Bring us your business question and our experts will help you scope it.